-
 DBFCSV: Conversion between DBF and CSV files
| Presentation and options | Dialog box of the application |
| Examples | Syntax |
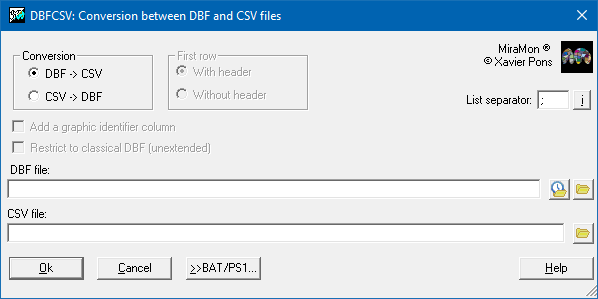
This application converts files from DBF format to CSV format and vice versa. TXT files are also supported as a tabular data format, both for reading and writing. The available options are:
In the DBF to CSV/TXT conversion, the data from the original table are transformed into a text file. In this file, the text appears on the same line, and the different columns or fields are distinguished by a separator character, which can be selected. In many European countries, the preferred separator is the semicolon (;), while the comma (,) is commonly used in the United States and many other countries. This separator can also be a tab character; in this case, the text TAB must be entered as the list separator. The tab character is an excellent (recommended) choice because reading CSV files in other programs (such as MS Excel itself) is much less problematic when fields contain commas, semicolons, quotation marks, apostrophes, etc. The special words SPA, to indicate that a space will be used as the list separator, and CAP, to indicate that there is no list separator, are also accepted.
The first row of the generated CSV will contain the field names, which will become the columns of the CSV file. The subsequent rows will contain the values of each record, separated by the selected delimiter.
In the reverse conversion, from CSV/TXT to DBF, you must select the separator used in the CSV to generate the different columns (if in doubt, you can open the file to check which separator is being used through the icon  or open it with any text editor; keep in mind that, if quotation marks are present, they normally delimit text that will be placed in the same field, or, when doubled (""), they indicate a single quotation mark that should be retained as a text character, typically to represent the arc-second symbol, or seconds as 1/60 of a minute).
The first row of the CSV may contain the column names (when First line with header is selected); in this case, these names can be used as the field names of the generated DBF. In this first row, the separator between the field names is the same as in the remaining rows that will become records. If the CSV file contains blank lines at the end, particularly due to a final line break, these lines are not added to the DBF as empty records. If these records without information are desired, as many separators as there are fields in the line must be written.
It should be noted that, in the case of CSV files, the program analyzes the file beforehand to determine the character set and determine whether the file is ANSI, OEM, or UTF-8. The output DBF table is written using the character encoding specified by the JocCaracDBFPerDefecte= key in MiraMon.par, which can be modified using a plain text editor or from the "Help | Configure parameters" menu, in the "Zoom and General aspects" tab.
In MiraMon, the main tables associated with files that are layers containing geographic or geometric content (graphic layers, etc.) are in DBF or extended DBF format, and always have a first column used to store what is known as the graphic identifier (ID_GRAFIC). This is used to provide each graphic object with a series of geometric-topological or thematic attributes. If the CSV does not have a first column of graphic identifiers, one can be generated by activating the "Add graphic identifier column" checkbox.
In addition, in MiraMon, DBF tables can exceed the limitations of the dBASE IV format (known as classic DBF; see the document dedicated to extended DBF -available in Catalan-), but this is not the case in other cases, such as tables corresponding to layers in Shape format. Therefore, the application provides the option to restrict the conversion from CSV to DBF to the limits of the classic DBF format (not extended); note that in this case, as expected, fields or parts of field contents may be lost, field names may need to be simplified, etc, because this information cannot be accommodated into a classic DBF.
It is also possible to specify which character is used as the text qualifier. In a CSV file, the text qualifier is used to delimit the beginning and end of text that is considered part of a column (which will become a field in the DBF). In other words, it indicates that everything between two qualifiers (for example, quotation marks or apostrophes) is part of the same field, even if it contains the character used to separate columns. This allows, for example, a text field to contain a comma when a comma has been specified as the separator, provided that the entire field content is enclosed in quotation marks, without the comma being interpreted as a column separator. For this purpose, the field content is enclosed between two characters known as text qualifiers.
MiraMon allows to select from 5 possible qualifiers:
For example, in a record containing three fields: a numeric field (1), a text field (Pinus, Abies, etc), and another numeric field (28), with quotation marks selected as the qualifier:
1,"Pinus, Abies, etc",28
the commas within the text "Pinus, Abies, etc" are not considered separators, since the text has been specified as being delimited by the qualifier, which in this case is the quotation mark.
Finally, MiraMon also allows you to specify how a double qualifier should be interpreted. When a CSV file contains a double qualifier (that is, two consecutive qualifiers: ""), it may refer to a field with no content, but it may also refer to the " character itself, as when a field contains coordinates in degrees-minutes-seconds and the seconds value is followed by the " symbol. In these cases, the CSV file may have been written using a double qualifier "" to prevent the seconds symbol from being interpreted as the beginning of new text marked by a qualifier. This option allows you to specify how the presence of a double qualifier should be interpreted:
The application also supports reading and writing metadata files in CSVW (JSON) format to document column properties, such as field name, data type, maximum width, units (if specified), etc. When converting a CSV/TXT file to DBF, after selecting the CSV/TXT file, the application automatically attempts to locate the corresponding CSVW file and, if found, assigns it to the corresponding resource and updates the options available in the dialog box (list separator, presence of a header, etc.). If no CSVW file is found, or the user does not specify one, the application automatically attempts to determine the list separator and whether the CSV/TXT file contains a header.

  |
| DBFCSV dialog boxes |
The following example shows the conversion of a DBF file containing information about a country's monumental trees.
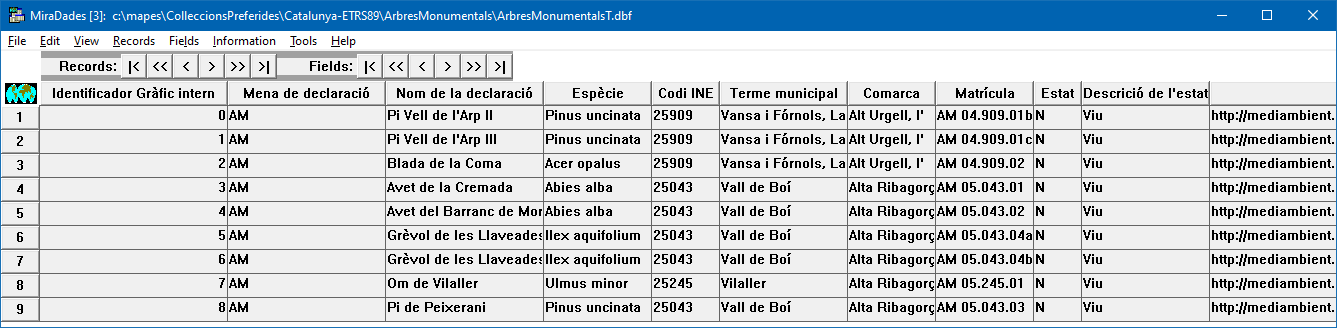 |
| Tabla DBF origen |
If the semicolon (;) is used as the separator, the header and the first row of data from the original DBF table containing the monumental trees are written as follows:
ID_GRAFIC;MENA_DECLA;NOM_DECLAR;ESPECIE;INE;TERME_MUNI;COMARCA;MATRICULA;ESTAT_DETA;ESTAT_RESU;URL;COORX;COORY;OBJECTID
0;AM;Pi Vell de l'Arp II;Pinus uncinata;25909;Vansa i Fórnols, La;Alt Urgell, l';AM 04.909.01b;N;Viu;http://mediambient.gencat.cat/ca/05_ambits_dactuacio/patrimoni_natural/arbres-monumentals/am_arbres_monumentals_fitxes/alt-urgell-6/pins-vells-de-larp-l-ll-lll/;377432.00;4673067.00;26
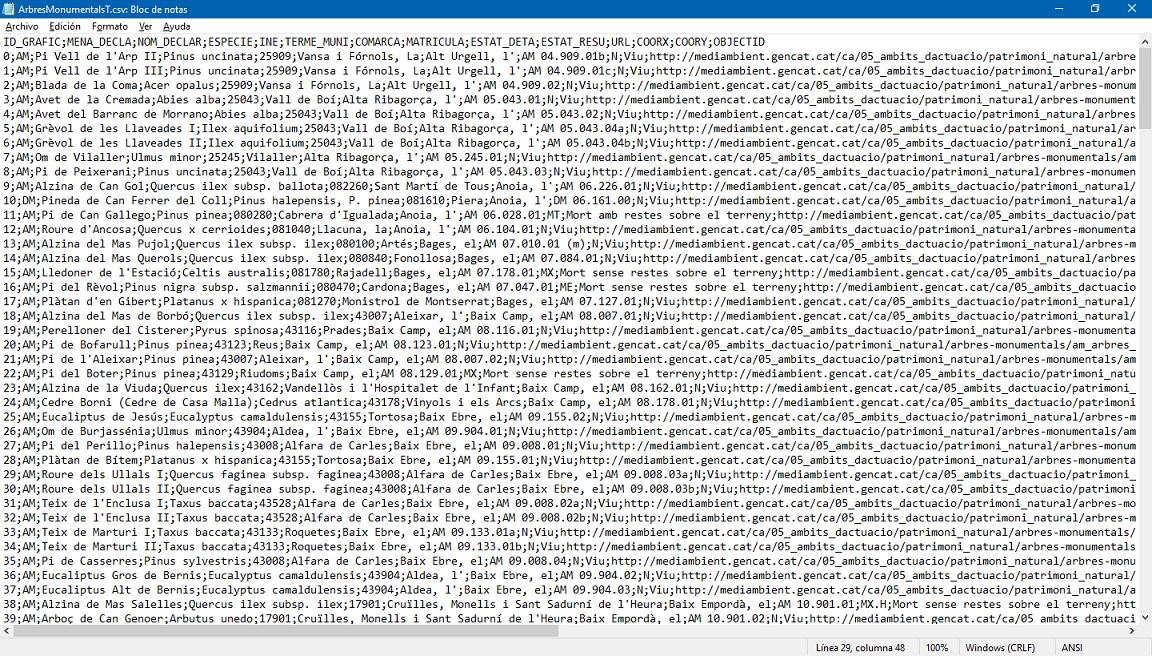 |
| Output CSV file |
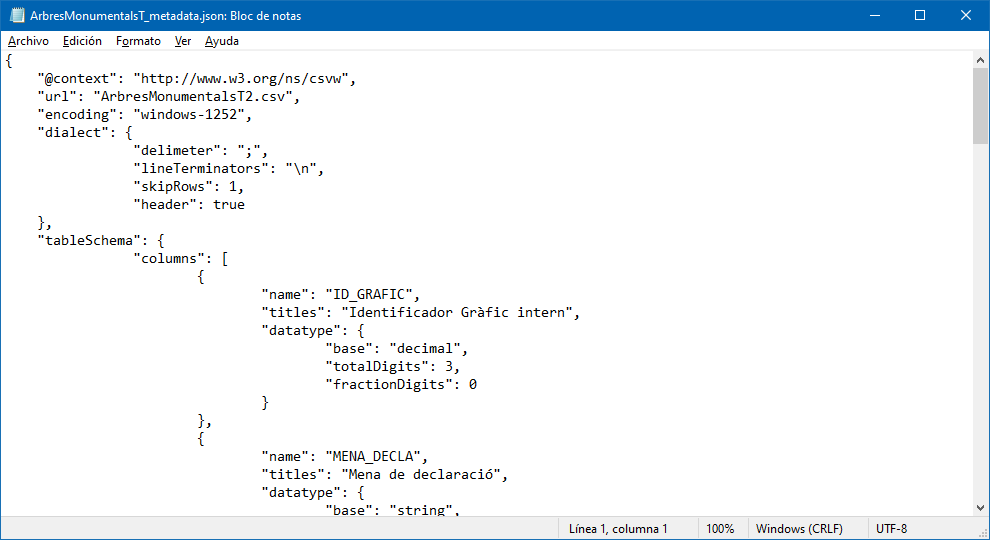 |
| Metadata file in CSVW (JSON) format |